ML & AI / Season 1 / EP09
Cross-Validation Data Leakage (Group Leakage)

Kurumi, meet our new star. "Model X."

Another one? What happened to Model Y?
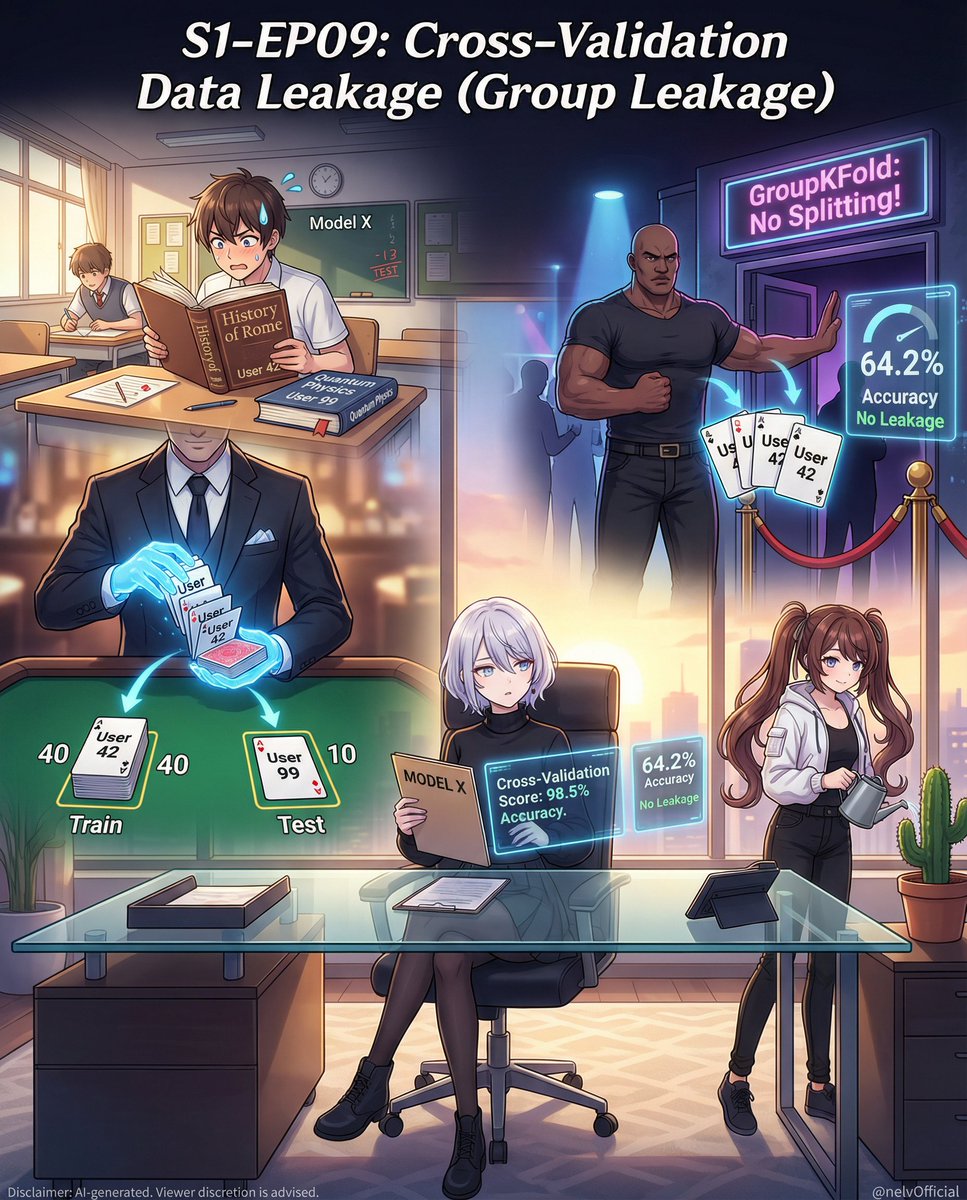
Model X is a genius! Look at that CV score! I ran a 5-Fold Cross-Validation. He predicted the customer behavior perfectly, 5 times in a row!
98.5%. Suspicious... Did you test him on *new* customers?
I tested him on the Validation Folds! That *is* unseen data!
`KFold(n_splits=5, shuffle=True)`.
Ah. I see. You didn't test him. You let him cheat.
Cheat? I shuffled the data! It's random! Randomness is the essence of fairness!
Randomness is the essence of leakage when your data has **Groups**.
How many rows of data do you have for User 42?
He's a power user. He has about 50 transactions in the dataset.
That is where the problem lies. When you shuffle randomly, where do those 50 transactions go?
Statistically, 40 of them go into the Training Set. And 10 of them go into the Test Set.
Yeah. So?
Imagine User 42 is a specific topic. Let's say "History of Rome."
Here are 40 questions about Rome to study.
(Reading) "Caesar died in 44 BC." "Nero played the fiddle." Got it.
Now, answer these 10 *new* questions about Rome.
Easy. "Who died in 44 BC?" It's Caesar. "Who played the fiddle?" It's Nero.
See? He learned History!
No. He memorized the **Subject**.
Now, send Model X into production. A new user signs up. User 99.
(Sweating) Uh...
I... I don't know who Caesar is in Quantum Physics.
He fails. Because he never learned *how to learn*. He just memorized that "User 42 likes Roman History."
This is **Identity Leakage**.
By putting pieces of User 42 in both Train and Test, the model learns to identify *User 42*, not the *purchase pattern*.
So my model is just... recognizing faces?
It's a "Who's Who" directory, not a predictive engine.
You validated the same customer five times. LinkedIn would clap. But in engineering, we call this **Overfitting**.
But I need to use all the data! How do I stop him from memorizing faces?
You need to respect the **Group Boundaries**.
If User 42 is in the Training Set, *every single transaction* he ever made must be in the Training Set.
The user must be invisible to the model during training if you want to test on them.
Oh! So when it sees the Test set, it's seeing a total stranger.
Exactly. Just like in Production.
`from sklearn.model_selection import GroupKFold`.
`cv = GroupKFold(n_splits=5)`.
`cv.split(X, y, groups=user_ids)`.
Make sure you pass the `groups` parameter. Otherwise, it just defaults to index splitting.
Got it. Passing `user_id`.
"Hold on, User 42. Your friends are already inside the 'Train' club. You have to go there too. You can't enter the 'Test' club."
But I want to be tested!
Not in this fold, buddy.
Okay... calculating...
NOOO! It ruined my model! It's garbage now!
(Sipping coffee) It didn't ruin your model. It revealed the truth.
That 64% is what you were *actually* going to get in production.
I just saved you from deploying a dud and getting fired next month.
Okay. 64% is bad. How do I improve the *truth*?
You do real engineering.
1. Feature Engineering that is **User-Agnostic**.
Don't use "User ID" as a feature. Use "Frequency of Purchase" or "Time Since Last Login."
Teach the model to look at the *behavior*, not the *identity*.
2. Aggregated Features. "Average spend of *similar* users."
Generalize. Don't memorize.
Removing `user_id` from features. Adding `rolling_mean_7d`. Adding `category_preference_ratio`.
Running `GroupKFold` again.
78%. It's... better.
And one more thing. Is your data **Time-Dependent**?
Uh... yeah. Transaction logs.
Then `GroupKFold` isn't enough. You need **Time Series Split**.
Why?
If you randomly split users, you might train on User B (who bought in 2024) and test on User A (who bought in 2023).
The model learns the future trends (e.g., "Macroeconomic Inflation") from User B and uses it to predict the past for User A.
Why is it so hard to stop the model from cheating?
You need to design smarter tests.
For now, `GroupKFold` is enough. Next time, we'll handle `TimeSeriesSplit`.