ML & AI / Season 3 / EP05
Monke Brain, Galaxy Brain, and Anti-Retard Filter

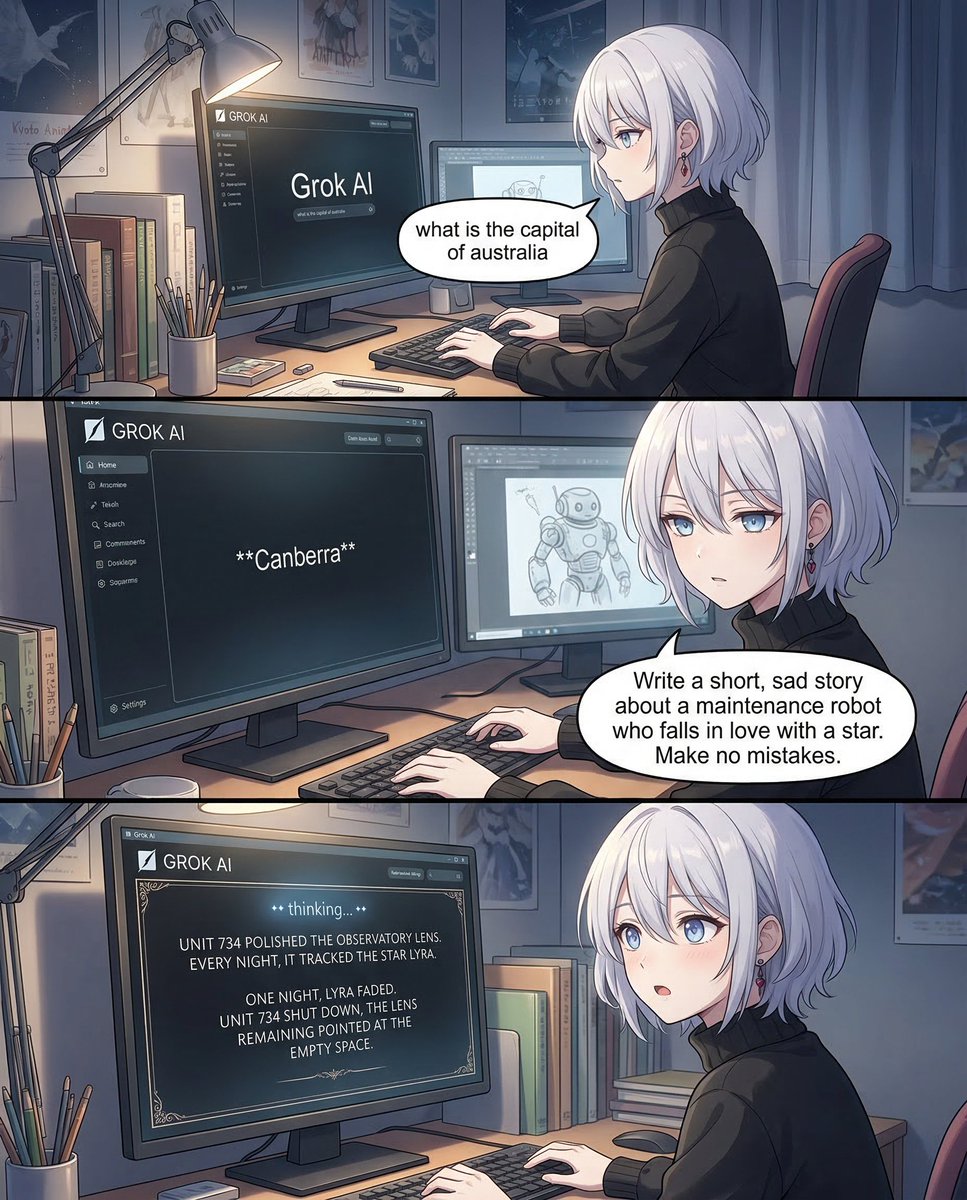
what is the capital of australia
Write a short, sad story about a maintenance robot who falls in love with a star. Make no mistakes.
I don't get it. Sometimes this thing is faster than my reflexes, like it's reading my mind. But then, sometimes it has to just... sit there and think?
Is it moody? Or are there, like, two different AIs—one for facts, and one for feelings?

It's not mood swings—it's a tiered system. You just used two different brains: the fast, cheap, Monke brain, and the slow, careful, Galaxy brain.
Wait—two brains? So... it's not just one giant AI doing everything?
Running a single, massive, brilliant AI for all tasks? That's just burning money! 90% of requests are as simple as 'what time is it?'—you don't need Einstein for that. A digital parrot is enough.
Here's the law of AI economics: **Never wake up the expensive brain unless you absolutely have to.**
This is the **Fast Brain**. Think of it as 'Gemini Flash' or 'Grok-4.1 Fast'. It's the front-line worker.
What makes it so fast?
It's a smaller, dumber version of the big model. It's been **quantized**. The complex, high-precision numbers that make up the AI's 'thoughts' have been compressed into lower-resolution integers. It sees the world in a blurrier, less nuanced way.
So it's faster because it's... dumber?
Fewer calculations, less memory, a fraction of the GPU cost per token. It's the **reflexive brain**
This is the **Slow Brain**. The 'Gemini Pro' or 'Claude Opus'. This is the full, uncompressed, high-parameter genius. The professor.
And it's slow because it's doing more math?
It has a vast number of parameters and operates at full precision. It can understand deep context, generate creative prose, and reason about complex problems.
But every one of those 'thoughts' is a computationally expensive matrix multiplication. It's a genius, but you pay for its time by the millisecond.
Okay, so there's a fast, dumb intern and a slow, expensive professor. But how does the system know which one to send my question to?
It uses a **Dispatcher**. A smart, cheap traffic cop.
The dispatcher is a small, fast model itself. It analyzes your prompt's complexity. Is it a simple fact? Is it short? Does it have low ambiguity? Send it to the cheap brain.
Does it ask for creativity, summarization, or complex reasoning? Send it to the professor and start charging for consultations by the second.
Wow. So it's an entire ecosystem of trade-offs, all designed to minimize cost.
But... all these brains, fast or slow... Where does their knowledge come from?
Well, they eat the internet. But lately they've been eating so much its becoming an existential threat to the future of AI.
What threat?
Right now, in 2026, the internet is still mostly filled with human-generated data. Messy, chaotic, beautiful, real data. This is the nutritious food the models were trained on.
But what happens when 90% of the new articles, blog posts, and images on the internet are generated by other AIs?
When the next generation of models is trained on the synthetic, recycled, and often soulless output of the previous generation...
It would... get worse?
It's a process called **Model Collapse**. Some researchers would call it 'Habsburg AI'.
Habsburg, like the royal family?
Exactly. The Habsburgs were famous for their generational inbreeding. AIs trained on their own output do the same. The forget the richness of reality and amplifying their own biases.
The AI starts eating its own tail. The signal is lost. The model's understanding of the world shrinks until it's just a blurry, inbred echo of an echo.
So that's it? AI is doomed to get dumber?
Not if the engineers are smart about it. In AI safety, we have **Data Provenance**.
Provenance? Like for art?
Yes. The new job of the 'Reranker' agent isn't just to find relevant information. Its most critical task is to determine if a piece of data is **'organic'** or **'synthetic'**.
They are building systems to watermark AI-generated content at a fundamental level. And the retrieval agents are being trained to see these watermarks. Every piece of data in the index is now given a 'Synthetic Score'.
So what happens to the synthetic stuff? Does it just get ignored?
Not always. Sometimes it's useful. But for training the next generation of 'professor' models, it's treated like poison.
This creates a new, strange economy. In a world flooded with infinite, cheap, synthetic text, the most valuable and scarce resource becomes... authenticated, high-quality, human-generated data.
The new gold rush isn't for bigger models. It's for cleaner data.
Wait a minute. That's a nice, clean diagram. But it's built on a childishly simple assumption.
Oh?
You're assuming the AI-generated content will politely announce that it's AI-generated. What if I take the story about the maintenance robot, change a few words, then post it on my blog under my own name?
The watermark is gone. My blog is a 'human' source. I've just laundered synthetic data back into your 'organic' training set. Now what?
Hahaha. Not a bad way to think.
A simple watermark is a flimsy chain-link fence. It keeps out the lazy, but not the determined. For bad actors, we have to deploy the forensic team.
Forensics?
When the retrieval agent pulls your 'new' story, it runs a second layer of analysis. It doesn't just look for a watermark. It analyzes the **style**.
Every AI model has a 'tell'—a statistical fingerprint. A bias towards certain sentence structures, a slightly-too-perfect grammar. Most popularly, the em-dash.
The forensic agent can detect that ghost in the machine. Your story gets flagged: 'PROBABILITY OF SYNTHETIC ORIGIN: 98.6%'. It gets down-ranked.
Okay, fine. So it's a cat-and-mouse game for laundered data. But there's a bigger problem. What about the *human* data? Is it really the 'nutritious food' you think it is?
Have you *read* the internet? 90% of 'organic human content' is garbage! It's my uncle's unhinged political rants on Facebook. It's LinkedIn bros posting motivational platitudes. It's Reddit arguments based on vibes instead of facts. It's poorly written, biased, low-signal slop!
You're telling me you'd rather train a superintelligence on Nigerian spam emails than a well-written, factual summary just because the summary was written by an AI?
Right. The true division is not **'Human vs. Synthetic'**. It is **'High-Signal vs. Low-Signal'**, and its a difficult curation process.
And how does it tell the difference?
It can never do it for certain. The simple way we've done is to use something like Google's PageRank system. An **Authority and Trust Graph**.
Think of it like the scientific community. A new paper is published. Who wrote it?
Are they a Nobel laureate or a first-year student? Where was it published? Who is citing this paper? Other respected scientists, or a bunch of random accounts on Twitter?
Besides, in most cases synthetic data are not outright rejected, and may even be actively favored, especially for privacy purposes. It is the distribution of data that AI is really looking for to get smarter.
People use synthetic data for NLP and CV all the time with a lot of success. Remember the **Model Distillation** we talked about for fast, quantized brain? Synthetic data are often used to lower the training cost.
So... the AI of the future won't be trained on the whole internet. It will be trained on a tiny, curated, 5-star corner of the internet, regardless of who or what wrote it?
It will be dependent on the trainer's objective. Does it want truth? Accuracy? Latency? This is how you create a **curation** process that is unbiased and slop-resistant.
So long as we keep coming up with novel ways of creating and curating knowledge, AI capabilities shouldn't plateau.