ML & AI / Season 3 / EP04
The Great Wall of Training (WMSS)

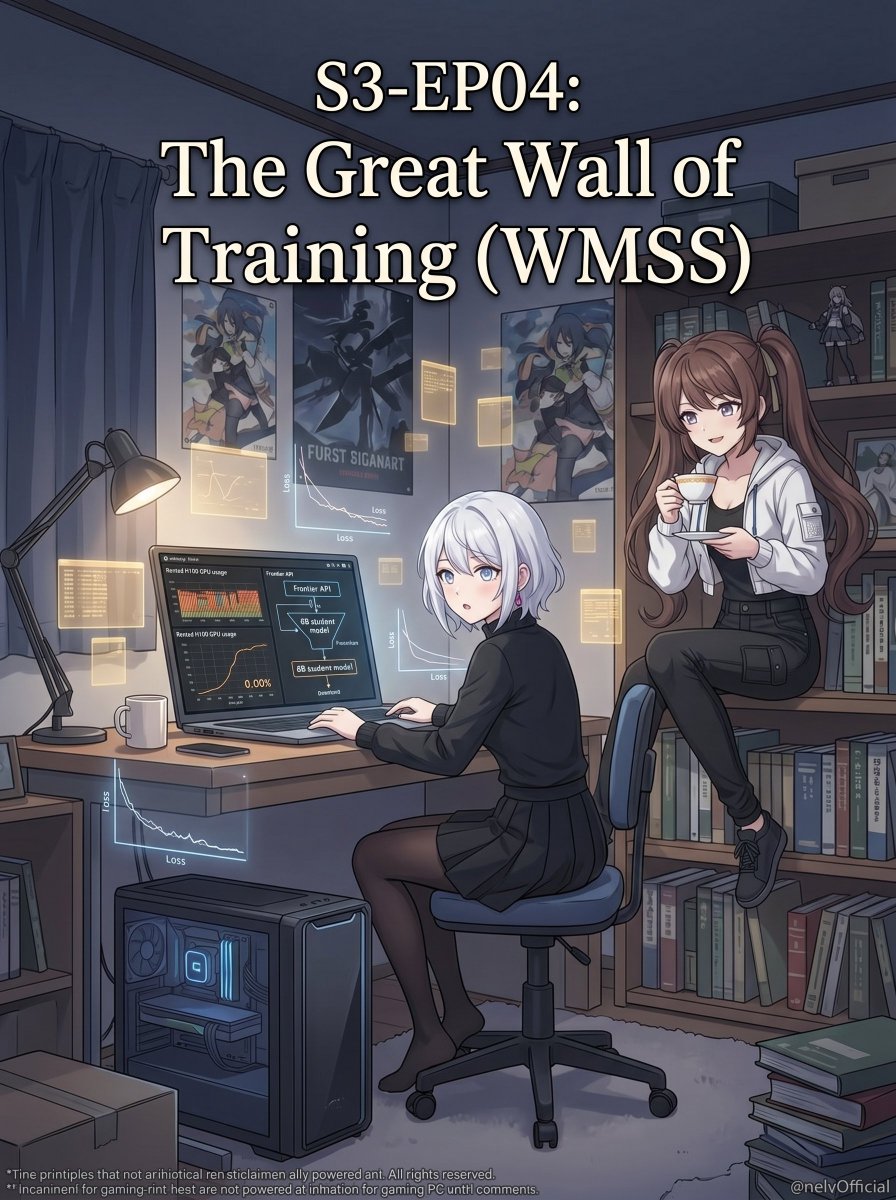
I'm doing knowledge distillation! I pay the big genius model to generate perfect answers, and I force my small model to memorize them. It's foolproof.

And how is your little synthetic parrot performing today?
It's stuck! For the first two days, it was getting smarter by the hour. Now? The accuracy hasn't moved a single percent!
Ah. You have hit the Great Wall of Training.
The Great Wall? It's literally reading the answers of a supercomputer! Why is it refusing to learn?!
Because it's already too confident. And in the world of neural networks, absolute confidence is the death of learning.
For years, the AI industry worshipped the gospel: Intelligence flows downhill.
You distill from bigger teachers. You fine-tune on perfectly clean data. You assume the only way to improve is to pay an expensive tuition to a celebrity professor.
But your model has absorbed all the basic patterns. When you feed it another correct answer, its internal math says, 'Yep, I already knew that.' The error rate is near zero.
But when the model's 'logits' (its raw prediction scores) saturate, it becomes highly confident on the training distribution. The slope disappears. The gradients shrink to near zero.
Great. So what do I do? Rent an even BIGGER teacher model? Buy more expensive data?
No. You fool. You stop looking up at the gods, and you start digging into the graveyard.
The graveyard?
I want you to load the checkpoint of your model from three days ago. The weak one. The one that failed half its math tests.
What?! NO! That version is garbage! Why would I pollute my current, smart model with the outputs of its dumb past self?
Have you ever heard of the Learning Pyramid?
The fastest way to master a skill isn't to passively watch a master. It's to critique your own past failures.
Imagine a master pianist. She's hit a plateau. Listening to more recordings of Mozart won't help her improve; her ear already knows what perfection sounds like.
Instead, she listens to tapes of her own past, weaker performances. The wrong notes. The hesitant phrasing. The overconfidence that masked deeper misunderstandings.
Those past embarrassments aren't trash. They are self reflections. They expose the exact, subtle decision boundaries that still need sharpening.
Wait... so this paper that just came out about in February 2026 by Beihang University and China Telecom...
WMSS. Weak-Driven Learning. The realization that weak agents can make strong agents even stronger.
Researchers learned that when your strong model looks at a difficult math problem, it confidently guesses the right answer. Gradient is zero. No learning.
But WMSS introduces 'Joint Logit Mixing'. You mix the thought process of the strong model with the thought process of the weak model.
The weak model still assigns high probability to 'hard negatives'—answers that look right but are fundamentally flawed. Traps it used to fall into.
By reintroducing those hard negatives, you suddenly reactivate the strong model's gradients!
The strong model is forced to say, 'Wait, I remember thinking that was the right answer. But it's wrong, and here is exactly why.' You redistribute the probability mass. You shatter the plateau.
Wow! From the benchmarks, standard fine-tuning barely moved the needle. But when they added the weak checkpoint via JTWS...
On the AIME 2025 math benchmark... performance almost doubled! From 12.2 to 20.0!
The best part? It doesn't require a trillion-parameter supercomputer for its data.
You are just changing the loss function during post-training. You are recycling your own developmental archaeology. The inference cost at runtime is literally zero.
We had it completely backwards. We thought the weak checkpoints were just stepping stones to be discarded.
Intelligence is dialectical, Shez. It requires periodic, deliberate introspection into earlier, more uncertain versions of itself. If you only ever reinforce what you know, you become drown in arrogance.
So, we can finally stop begging stronger gods for wisdom!
For those who know how to build, yes. The frontier labs aren't just hoarding data anymore. They are mining their own historical logs.
The models that master this won't just be larger. They will be wiser, because they have learned how to learn from weakness itself.